TypeSafe announced Jev on 15 September. We got our hands on it on 28 September and had it in production the same day, as the judge of the plans InstantClips drafts for sellers' product videos. Jev costs 97 per cent less than the large language model (LLM) judge it replaced and answers almost 20 times faster.
That is not all. Jev is a different kind of model. It answers questions with numbers and writes nothing. Asked twice, it gives nearly the same answer. Its confidence drops where it lacks the evidence. Together they let us run consistent brand checks and automatic quality assessment on every asset a workflow produces. The rest of this post is the evidence.
Brand checks and quality assessment on every asset
The same check on every bottle.
The reason this matters to a brand is what a workflow can now check, and who checks what. Literal rules go to code: is the approved product name present, is a banned word absent. Anything visual goes to a vision model first, which describes the frame. Everything between those is Jev's: is this caption in the brand's voice, does this plan lean on stock adjectives, does this script promise more than the brief, is this opening the kind the brand approved. Those are judgement calls, and on a text plan they now cost a fiftieth of a cent and half a second each. An image or video adds the cost of describing it first.
We are putting that division into the Creative Workflows we run for clients. A check that comes back with low confidence goes to a person. The rest are recorded against the asset, and a client's brand rules, approved once (Approve the workflow once), are enforced on everything the workflow produces.
What Jev is
Every question takes one of the three forms above, and Jev returns numbers and nothing else: no explanation, no prose. It reads text only, and TypeSafe says images are not supported yet.
How we use it
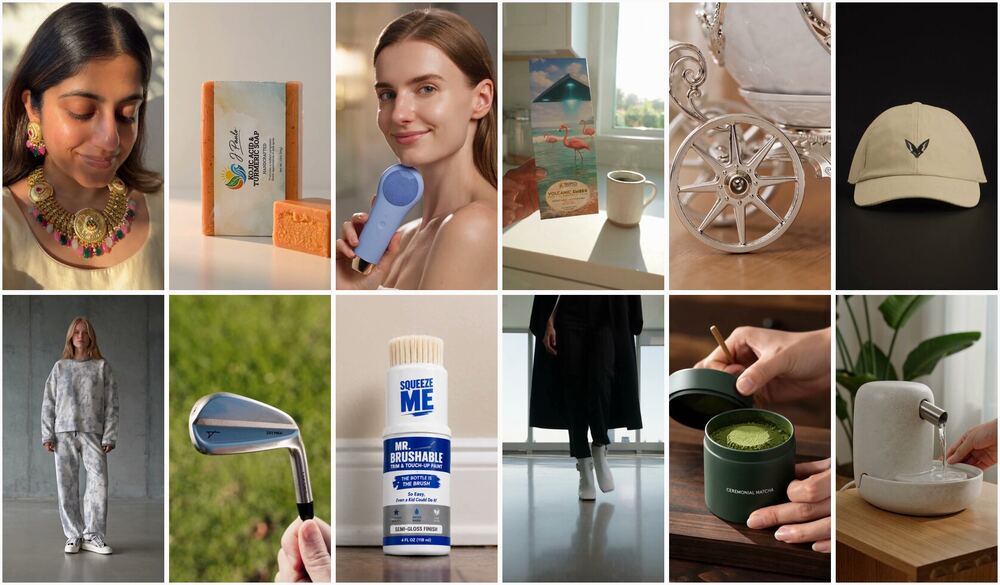
Twelve ads from the InstantClips example library.
InstantClips drafts a plan for each product video, and the seller approves it before anything renders. Jev judges every draft of that plan on 24 questions, from how strong the opening is to whether the seller's brand is named, and picks the better of two versions when we change the prompt that writes the plan. So far that is 1,800 drafts and 900 pairs, with the LLM judge it replaced run alongside for comparison. Day one was possible because on our platform the judge is one step in a workflow, and a step can point at a new model with nothing else changing.
What it costs, and what that changes
Jev costs 97 to 98 per cent less than the LLM judge and answers in half a second against five to ten seconds. A million judgements cost under two hundred dollars, against six to twelve thousand.
At that price a judgement is effectively free, and that changes what gets measured. We judge every draft of every prompt build, ask every pair of plans both ways, and judge drafts twice to check that the answers hold. None of it shows up on a bill. When the judge cost thirty to sixty times more, measuring was something we scheduled. Now it runs on everything, every time.
DeepSeek is nearly free too, but it still writes text.
DeepSeek V4.1 Flash works out at roughly $0.001 to $0.004 a judgement at list price, nearly free as well, and it can return JSON. What it does not return is a probability over every level and a confidence. Its thinking mode is also on by default, and until it is turned off it spends tokens before the answer starts, in amounts it does not control. InstantClips ran on DeepSeek V4 Flash until July, and for an identical prompt it spent anywhere from zero to 260 tokens thinking before a 30-token answer. We turned thinking off, then switched models.
Nothing to parse
Our old judge wrote its scores as a JSON block, which we pulled out of the reply with a pattern match and parsed, and now and then that failed. Schema-constrained output would remove most of that at the same price and speed. What it would not give us is what Jev returns natively: a probability for every level and a confidence, in half a second, for a fiftieth of a cent. Across 1,800 drafts not one Jev answer came back unusable.
Nearly the same answer twice
Asked the same 24 questions about the same draft twice, Jev moved each score by 0.02 to 0.09 on a scale of 1 to 5 and changed 2 per cent of the yes-or-no answers, all of them close calls. That is not identical, and it is close enough to use a score as a measurement: change the prompt, judge again, and read any difference bigger than a tenth as the prompt's doing.
Its confidence tracks the evidence
Every Score and Choice answer comes with a confidence, TypeSafe's measure of how concentrated the answer is on one level, from 0 to 1. In our data it tracks the evidence available to Jev. On the four questions the text alone can answer, its reported confidence was 0.7 to 0.8. On the three that need the photo it cannot see, or a check across two parts of the text, it was under 0.4, and 86, 92 and 97 per cent of answers came in under 0.5, the level at which TypeSafe's own guidance says to route to a person. Its misses fall in the same place, so we answer those questions another way, with a text search and with a judge that can see the photo.
What to design around
Three things, each with a mechanical fix, and each one showed up in Jev's own confidence first. Order: ask every pair both ways and average the two. Absence: a text search answers whether a word is present or missing, and Jev gets the questions that need judgement. Sight: whatever needs the image goes to a model that can see, or to a person.
How we measured
Native Jev, jev-1.13.0, over TypeSafe's API, text only.
Four test runs on 60 real seller inputs, three drafts each per prompt version: 1,800 judged drafts and 900 pairs of plans.
Repeat probes: 30 drafts judged three times over, and 30 pairs asked in both orders three times over.
Against the previous judge, Claude Sonnet 5 writing JSON: the same verdict on 62 per cent of 180 pairs, and 92 per cent where Jev's margin was 0.9 or wider. No human labels, so agreement is not accuracy.
Latency: median 0.53 s, slowest 5 per cent 1.7 to 7 s by hour. Failures: 0 to 8 network errors per 360 calls, retried. No unusable answers.
Production here means the judge that gates every change to the prompt that writes InstantClips' plans, run on real seller inputs. It does not yet score live seller drafts as they are made.
Since July we have said that no single model wins every job (One brief, five image models). Jev is the clearest case yet: a model that cannot write a sentence, doing a job the writing models did slower, dearer and with less consistency. If your brand rules are written down, they can be asked as questions. Talk to us about running them on your own work.
We design and run managed Creative Workflows for brands and agencies, with brand checks and quality assessment built into the line. Talk to us about running them on your work.